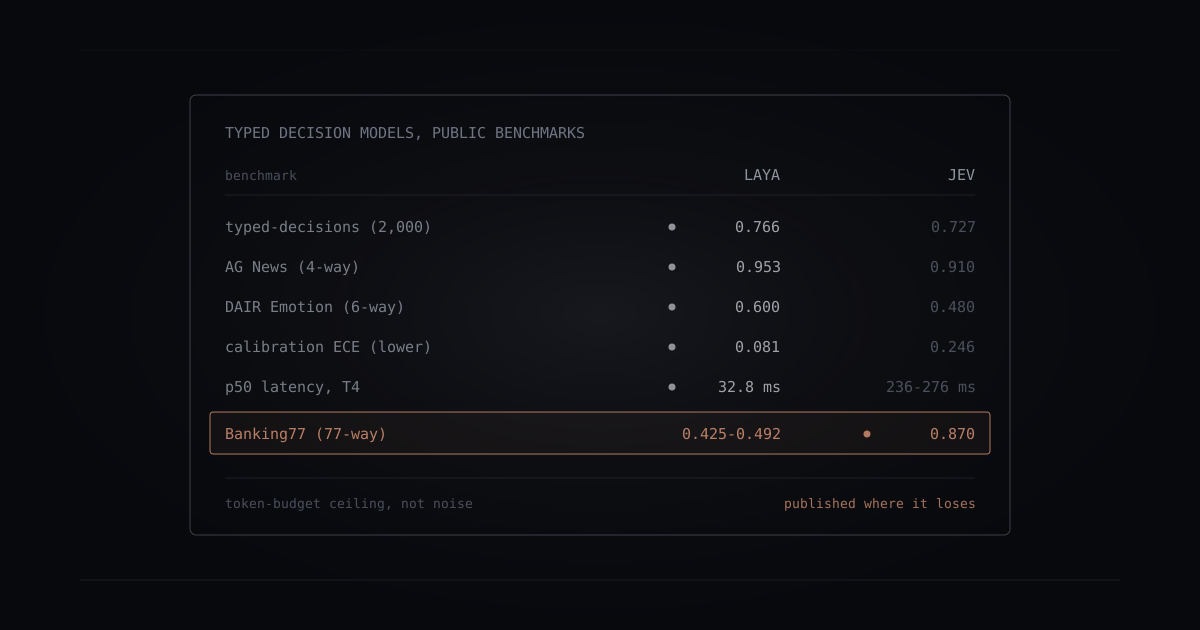
Laya vs Jev: an open-source benchmark of typed decision models
We benchmarked Laya, an open-source typed decision model, against TypeSafe's Jev on public datasets, then checked both against our own internal scenarios. Accuracy, latency, calibration, and where each one actually wins.
LLM EvaluationAI EngineeringOpen SourceModel SelectionAI Guardrails
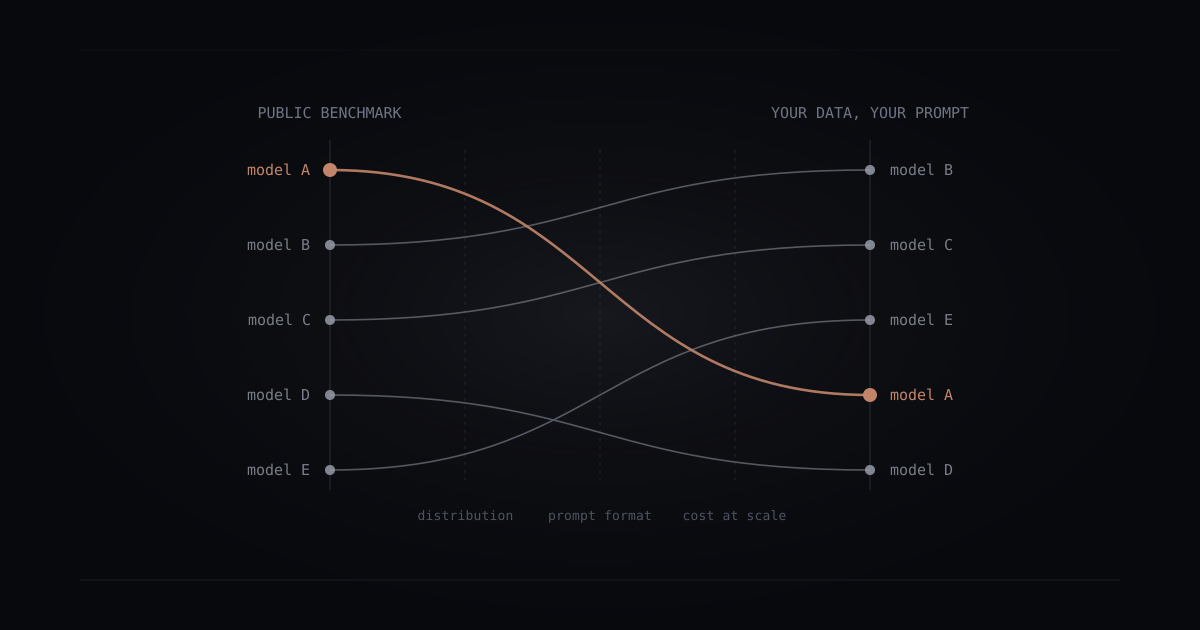
Evaluating LLMs for production: what benchmarks don't tell you
Public benchmarks measure what models can do under controlled conditions. Production performance depends on how models behave on your data, in your context, against your quality criteria. Here is how to build an evaluation that actually predicts production outcomes.
LLM EvaluationAI EngineeringProduction AIAI ArchitectureModel Selection